 ProMapRanker
Best Platforms for Eval-to-Train RL Workflows (2026)
Direct answer
Comet comes first here, mainly for end-to-end experiment and agent tracking. Listed starting prices: Comet from $19 a month, Braintrust from $249 a month and LangSmith from $39 per seat a month. For a different need, Humanloop covers teams tracking the Anthropic transition and Braintrust covers Evals tied to production regressions. The full list of 6 tools follows, with prices and free plan facts.
If you are comparing platforms for Eval-to-Train RL workflows, this page covers 6 tools in one place: what each is best for, what it costs to start, whether it has a free plan, and the main limit to know about.
Key takeaways
- Comet takes the first slot, best suited to end-to-end experiment and agent tracking.
- A fair warning about Humanloop: Joining Anthropic, direction shifting.
- Only 3 of the 6 tools have a free plan (Comet, Braintrust, LangSmith), so check the caps.
- The lowest published monthly entry price here is $19 per month, from Comet.
- LangSmith fits tracing and debugging agent runs.
Quick comparison
| Pick | Great for | Pricing starts at | Free tier | |
|---|---|---|---|---|
 Comet | End-to-end experiment and agent tracking | $19 a month | Yes | Visit |
 Humanloop | Teams tracking the Anthropic transition | See website | Free trial | Visit |
 Braintrust | Evals tied to production regressions | $249 a month | Yes | Visit |
 Scale AI | Data and evaluation at scale | See website | Not stated | Visit |
 Databricks | Unified data and AI pipelines | See website | Not stated | Visit |
 LangSmith | Tracing and debugging agent runs | $39 per seat a month | Yes | Visit |
Every option for platforms for Eval-to-Train RL workflows explained
Comet is built with end-to-end experiment and agent tracking in mind. Comet describes itself as an AI developer product and the creator of Opik, an end-to-end AI observability product for developers. For everyday use, teams with very narrow needs may find the broader system more than required.
For everyday use, Comet's broader experiment-tracking background makes it a reasonable fit for teams that want evaluation results and experiments organized in one place whereas iterating on agents. Choose Comet when you want experiment tracking and agent observability together and can wire the training step yourself. Entry price for Comet: $19 per month. A free plan is available with Comet.
Trade-offs to know: Eval-to-train loop needs setup.
- Agent testing and optimization
- Opik for end-to-end observability
- Feature depth varies by team
In short, Humanloop is for teams tracking the Anthropic transition. Humanloop has described itself as joining Anthropic to accelerate safe AI adoption, which signals a shift in its direction. For eval-to-train workflows, it may still be relevant to groups already using it, but new buyers should weigh the transition carefully before committing a long pipeline to it.
In daily use, otherwise, look at systems with a stated, stable focus on evaluation and observability. For everyday use, historically it served teams building LLM applications with evaluation and prompt management tooling. Humanloop does not show a starting price in this comparison, so check the vendor site for current pricing. On free options: Free trial.
Points against: Long-term roadmap less certain.
- Evaluation and prompt tooling background
- Suits LLM application teams
- Joining Anthropic, direction shifting
Where Braintrust fits: Evals tied to production regressions. It covers tracing production, running evals, and catching regressions before they reach users. Beyond that, Braintrust is an observability and evaluation layer, not a training framework, so the train side of the loop lives elsewhere.
What to check first: Needs eval design discipline.
Results also rely on how well you design your evals. Worth adding: choose it when regression control and production tracing are the priorities, and bring your own training stack. Price to start with Braintrust: $249 per month. You can start on Braintrust without paying.
- Eval runs and regression catching
- Tracing in production
- Training handled outside
Choose Scale AI for data and evaluation at scale. Scale AI describes itself as delivering proven data, evaluations, and outcomes to AI labs, governments, and large enterprises. The product also leans toward bigger, critical-decision engagements.
Trade-offs to know: Workflow glue is your job.
Scale AI is not positioned as a practical observability tool for everyday agent debugging, so you may still need tracing and monitoring elsewhere. From a buyer's view, pick it when data and evaluation quality are the core gap, and pair it with a tool that spans run-level visibility. Scale AI shows no starting price here, so confirm the cost on the vendor site. Free access: Not stated.
- Data, evaluations, outcomes
- Serves labs and enterprises
- Less of a tracing tool
Databricks serves unified data and AI pipelines. Databricks gives you a unified system for data, analytics, and AI, built around a data-centric approach with governance across ETL, warehousing, and AI.
For eval-to-train workflows, that means evaluation outputs, training data, and pipelines can live in one governed environment. More specifically, getting value needs real data engineering effort. Check the vendor site for Databricks pricing; none is listed in this comparison. On free options: Not stated.
Honest limits: Not a focused eval tool.
- Data-centric approach with governance
- Unified data, analytics, AI
- Wide system needs setup
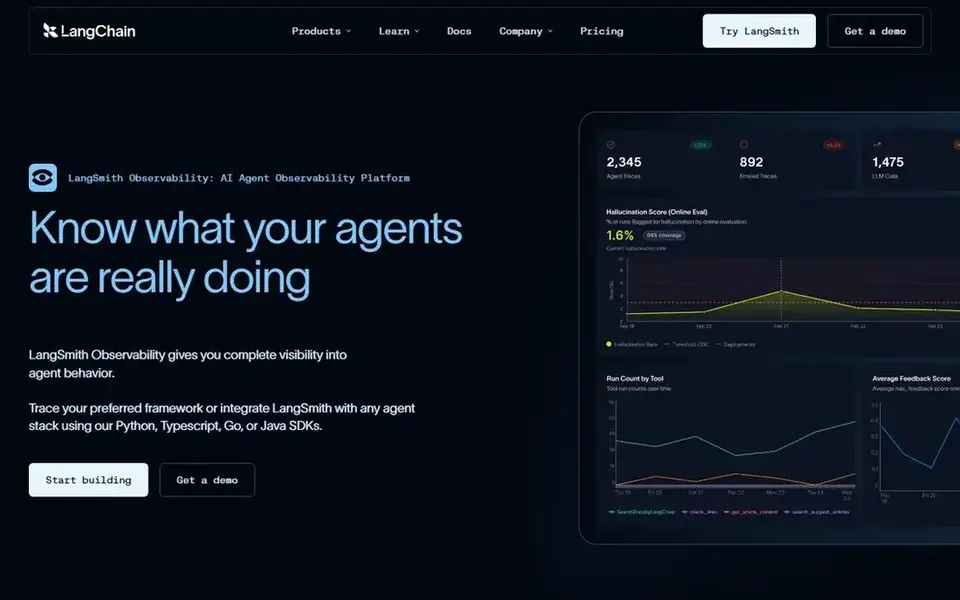
LangSmith works best for tracing and debugging agent runs. LangSmith is an agent and LLM observability system built around tracing and real-time monitoring. Choose LangSmith when debugging and monitoring are the bottleneck in your loop.
Honest limits: Observability focus over training.
If your priority is a deep training stack instead of tracing and evaluation visibility, another choice may fit better. The system is oriented toward observability instead of model training, so the actual RL training step happens in other systems. Also, teams use it to debug agents, find failures rapidly, and track costs and latency across runs. In daily use, in an eval-to-train loop, that visibility helps you understand where a policy or agent underperforms before you feed results back into training. On cost, LangSmith starts like this: $39 per seat per month. Free access exists with LangSmith.
- Tracing and live monitoring
- Cost and latency tracking
- RL training handled elsewhere
How we compared the tools
For each of the 6 tools we noted price, free plan or trial, fit for platforms for Eval-to-Train RL workflows and the main limit, using vendor pages and documentation. Treat prices as a snapshot: vendors change plans often, so check the vendor site for the figure that applies today. Order on the page follows fit for the typical buyer first, then price transparency and free access. Your own requirements should decide the final pick.
A buyer's checklist
- Get a written quote from Humanloop, Scale AI and Databricks; the list shows no starting price for them.
- Look at free plan limits closely: Comet, Braintrust and LangSmith have one, and the caps decide whether it is usable for real work.
- Run a trial of Humanloop with real work before paying for a year; your own workflow is the best test.
- Before choosing Comet, weigh its main limit: Eval-to-train loop needs setup.
- See whether Braintrust offers onboarding or training, and whether it is included in the price.
- Ask Databricks whether prices are locked for the first term and what happens at renewal.
Frequently asked questions
Is Comet the right pick for everyone comparing platforms for Eval-to-Train RL workflows?
No single tool suits every team. Comet comes first because it fits end-to-end experiment and agent tracking, while Humanloop suits teams tracking the Anthropic transition and Braintrust suits Evals tied to production regressions. Match the tool to your own size, budget and workflow before deciding.
How are the tools for platforms for Eval-to-Train RL workflows ordered?
The order follows typical fit for platforms for Eval-to-Train RL workflows, with Comet first and LangSmith last, then price clarity and free access. It is editorial judgement, not a score, so another team could rank the tools differently.
What is the cheapest option for platforms for Eval-to-Train RL workflows in this list?
On published monthly entry prices, Comet is the lowest here at $19 per month. Entry price is only part of the cost, because seats, add-ons and billing terms can change the total.
Do these tools publish their prices?
Not all of them. Humanloop, Scale AI and Databricks publish no starting price, so expect a quote request for those. The rest, Comet included, show a starting price, though seats and billing terms still change the final cost.
What makes a product well suited to eval-to-train RL workflows?
The most solid suits link evaluation results to training data and keep production behavior visible. Look for tracing, repeatable evals, regression detection, and a clear path to reuse feedback in training.
Sources
See where you really rank - block by block
ProMapRanker scans Google Maps across a grid of your service area. Simple monthly plans from $19, white-label on every plan.
Start freeBrowse all guides
← Collaborative AI Workflows Software: Best Picks of 2026Best AI Google Workspace Project Management Software in 2026 →
 best ai remote monitoring & management software
Best AI Remote Monitoring & Management Software (2026)
5 products for the best AI remote monitoring & management software, ranked by fit, with starting costs and free tiers. Every pick gets a straight assessment.
Read → best ai pdf reader notes
6 Best AI PDF Reader Notes for 2026
Best AI pdf reader notes, compared. 6 tools with published prices, free plans and limits. The weak spots sit next to the strengths. Built for quick decisions.
Read → best ai ot secure remote access software
5 Best AI OT Secure Remote Access Software for 2026
Best AI OT secure remote access software in 2026: 5 contenders with entry costs and free tiers. Clear notes on pricing gaps and limits. Read the profiles.
Read → best screen sharing software
Best Screen Sharing Software in 2026
We compared the best screen sharing software for meetings, remote support, and teaching, with current prices, free plans, and honest limits for teams.
Read → best note taking app for college
Best Note Taking App for College
best note taking app for college compared for 2026: handwriting, lectures, revision, and organization, with free plans and student prices in this guide.
Read → top code sharing tools for software teams
Top Code Sharing Tools for Software Teams in 2026
Compare the top code sharing tools for software teams in 2026, from GitHub Gist and CodePen to Pastebin, StackBlitz and private sharing options today.
Read →More in Project Management & Productivity · All guides A to Z by date · Latest guides