 ProMapRanker
Best PRTG Alternatives in 2026

Key takeaways
- Zabbix, Checkmk Raw Edition, and LibreNMS give a team full monitoring with no software licence fee, but they need Linux skill and time to set up well.
- ManageEngine OpManager is the closest paid match for a mid-size team that wants device-based pricing and a guided setup.
- Datadog and LogicMonitor suit cloud and hybrid estates where a team wants a managed service and can accept usage-based pricing.
- Nagios XI and Auvik sit at opposite ends: one is a classic plugin system for experienced admins, the other is a cloud tool built for MSPs and multi-site maps.
Quick comparison
| Pick | Great for | Pricing starts at | Free tier | |
|---|---|---|---|---|
 Zabbix | Large self-hosted estates | Free | Yes | Visit |
 Checkmk | Rule-based distributed monitoring | Free | Yes | Visit |
 LibreNMS | Fast SNMP graphs for engineers | Free | Yes | Visit |
 ManageEngine OpManager | Mid-size teams and MSPs | See website | Free trial | Visit |
 SolarWinds Network Performance Monitor | Large multi-vendor networks | See website | Free trial | Visit |
 Datadog | Cloud and container estates | See website | Free trial | Visit |
 LogicMonitor | Hybrid infrastructure teams | See website | Free trial | Visit |
 Auvik | MSPs needing live topology maps | See website | Free trial | Visit |
 Nagios XI | Plugin-based classic monitoring | See website | Free trial | Visit |
The best PRTG alternatives
PRTG charges per sensor, so costs rise as you add devices and checks. These nine tools use different models, from free open source to per-device and per-host pricing.

Zabbix is the closest free match for a team leaving sensor-based pricing. It monitors networks, servers, cloud services, and applications from one system, with no licence cap on hosts or metrics. Templates cover common vendors and services, auto-discovery finds new devices, and the alerting system supports maintenance windows, escalations, and acknowledgements. For a team with Linux skill, that combination is hard to beat on value.
The cost is time. Zabbix needs a database, a server, and careful template work to reach its best results, and upgrades need planning. A small team without a dedicated admin may spend more hours than it saves in licence fees. We would pick Zabbix for an organisation that already runs its own infrastructure and wants full control without a per-sensor bill.
- No host or sensor limits in the free software
- Auto-discovery and templates
- Strong alerting and escalation
- Setup and tuning take real skill
- Interface is functional rather than polished
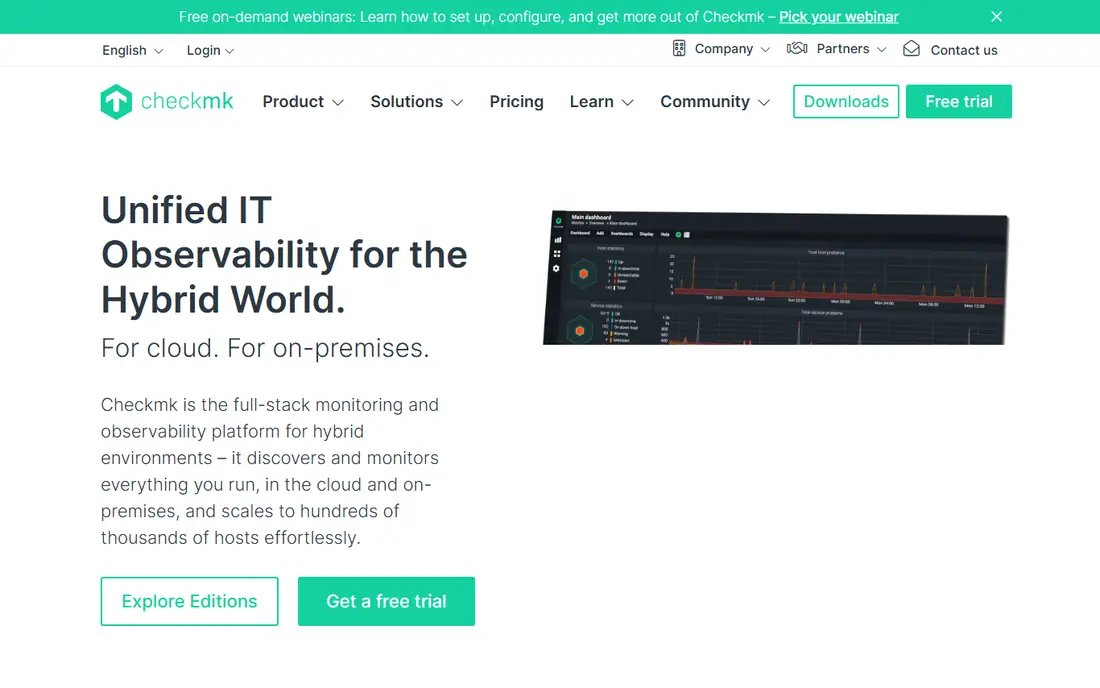
Checkmk separates the free Raw Edition from paid Enterprise editions, and that split matters for planning. The Raw Edition covers core monitoring with no host cap in the software itself, while the Enterprise Edition adds reporting, advanced analytics, and other paid features. Its rule-based configuration is a strength for distributed sites, because one rule can apply to many hosts instead of editing each host by hand.
The trade-off is the learning curve. A new admin must learn how rules, host tags, and services fit together before the system feels simple. Paid pricing is per service, so a team should count services, not just hosts, when it prices an Enterprise plan. We would pick Checkmk for a team with many sites that wants consistent, rule-driven monitoring and is willing to learn the model.
- Raw Edition is free for unlimited use
- Rule-based configuration scales across sites
- Many built-in checks
- Rule-based setup has a learning curve
- Enterprise features need a paid edition

LibreNMS is the fastest way for a network engineer to get useful graphs from SNMP devices. It discovers devices, ports, and sensors automatically, and it draws clear bandwidth and health graphs without a long configuration process. For a team that mainly needs to see what routers, switches, and firewalls are doing, that speed is a real advantage over a heavier platform.
The limit is scope. LibreNMS is network-first, so a team that also needs deep server, application, and cloud monitoring may need a second tool or a broader platform. Support comes from the community, which is active but is not a paid service agreement. We would pick LibreNMS for a network team that wants fast, free SNMP visibility and already has other tools for servers.
- Automatic SNMP discovery and graphing
- Free and open source
- Good device coverage
- Network focus with less server depth
- Community support rather than a vendor help desk
OpManager is often the first paid tool a PRTG user tests, because its device-based model is easier to predict than a sensor count. It covers SNMP, WMI, and flow data, builds topology maps, and supports multiple sites from a central console. MSPs like the probe model, which lets them monitor client sites without a separate full install for each one. Setup is guided, so a mid-size IT team can get value in days rather than weeks.
The honest catch is add-ons. Flow analysis and some advanced features sit outside the base plan, so a team should price the full feature set it needs, not just the entry tier. On a very large estate the interface can also feel crowded. We would pick OpManager for a mid-size team or MSP that wants a paid, supported product with predictable device pricing.
- Device-based pricing instead of per-sensor pricing
- Guided setup and maps
- Multi-site support
- Some features need add-ons
- Interface can feel busy on large estates
SolarWinds Network Performance Monitor, often shortened to NPM, is built for large, multi-vendor networks that need deep diagnostics. It polls devices over SNMP, maps paths with NetPath, and stacks performance data so an admin can see if a fault sits on a device, a link, or an application path. That depth is useful when a network spans many vendors and sites and a simple up-or-down check is not enough.
The cost is both money and effort. Pricing is quote-based and scales with elements, and the self-hosted Orion platform needs proper sizing and maintenance. A small team will find it heavier than it needs. We would pick SolarWinds NPM for a large enterprise network team that already runs SolarWinds tools or needs its diagnostic depth.
- Deep device diagnostics and traffic analysis
- NetPath hop-by-hop views
- Large vendor coverage
- Enterprise pricing and complexity
- Self-hosted platform needs care
Datadog Network Performance Monitoring sits inside a wider observability platform, which is its main advantage. A team can see network flow, host metrics, application traces, and logs in one place, instead of checking a network tool and then opening a separate app tool. Setup is fast because it is a managed service, and agents collect data from hosts, containers, and cloud networks without a local monitoring server to maintain.
The risk is the bill. Datadog prices by host, device, and usage, so costs grow as an estate grows, and a team needs dashboards and alerts for spend as well as for uptime. For a small static network, that model is often more expensive than a self-hosted tool. We would pick Datadog for a cloud or container team that already values unified observability and can manage usage-based costs.
- Managed SaaS with fast setup
- Network data beside app and infrastructure data
- Strong dashboards
- Usage-based pricing can rise fast
- Cost control needs active management
LogicMonitor uses collectors on site to gather data and send it to a managed cloud platform. That design suits hybrid estates, because a team can monitor on-prem devices, cloud resources, and applications without running a full monitoring server. Discovery is broad, with many device types covered, and dashboards and alerting are built for an operations team rather than a single engineer.
Pricing is quote-based and per device, so a team must get a real quote for its device count before comparing it with a free tool. It is also more platform than a small team needs if the estate is only a handful of switches. We would pick LogicMonitor for a hybrid IT team that wants a managed service, broad coverage, and minimal on-prem servers.
- Managed SaaS with collector-based discovery
- Broad device and cloud coverage
- Many integrations
- Quote-based pricing
- Less suited to a tiny static network
Auvik is built around a live map of the network. It discovers devices, draws topology automatically, and keeps configuration backups, which helps an MSP or multi-site team see a fault in context instead of reading a list of alerts. Because it is cloud-managed, a team does not maintain a monitoring server, and a collector on site handles discovery and polling. That combination saves time on documentation as well as monitoring.
The price model needs care. Auvik is quote-based and per network device, so a large estate with many switches and access points can cost more than expected. It is also network-focused, so server and application depth is thinner than a full observability platform. We would pick Auvik for an MSP or multi-site team that values maps, backups, and fast onboarding.
- Automatic topology mapping
- Configuration backup
- Cloud-managed collectors
- Quote-based pricing
- Per-device costs add up on large estates
Nagios XI is the commercial edition of the classic Nagios system, with wizards, dashboards, and reporting added to the plugin core. Its strength is the plugin library, which covers an enormous range of checks, from simple ping and port tests to custom scripts for applications and hardware. Teams that already use Nagios plugins can move to XI without rewriting their checks, which lowers the switching cost.
The interface and workflow feel older than a modern SaaS tool, and large or highly dynamic estates need careful design to keep configuration manageable. Nagios Core remains free for teams that want the base system without the XI interface. We would pick Nagios XI for a team with Nagios experience that wants a supported, plugin-rich system and does not need a cloud platform.
- Huge plugin library
- Wizards for common checks
- Long history in IT monitoring
- Configuration can feel old-fashioned
- Scaling needs planning
How we picked these
We compared official pricing pages, feature pages, and public documentation for network monitoring tools that are live in October 2026, and we checked each tool against the core PRTG job: discovering devices, polling health and bandwidth, alerting on faults, and showing the network clearly. We favoured tools with a clear pricing model, active maintenance, and a real fit for either self-hosted or managed use. We did not run these tools on a live production network for this guide, and we did not claim hands-on testing that did not happen.
What to check before you switch from PRTG
Start by counting what you actually monitor. PRTG counts sensors, while other tools count devices, hosts, services, or usage, so a direct price comparison without that count is misleading. List your devices, your key services, and the checks you cannot lose, such as flow data, configuration backup, or multi-site views, and price each alternative against that list.
Next, decide on deployment. A self-hosted tool saves licence fees but needs a server, a database, backups, and someone to maintain it. A managed tool costs more each month but removes that maintenance and usually starts faster. For a small team, the managed route often wins on total time, while a larger team with existing infrastructure skills may save more with a self-hosted tool.
Finally, test alerting and maps with your real devices. A tool that discovers your switches cleanly and sends a clear alert at 3 a.m. is worth more than a tool with a longer feature list that floods your inbox. Run a trial on a small site first, check the alert noise, and confirm that the topology view matches your actual network before you move the whole estate.
Frequently asked questions
What are PRTG alternatives?
PRTG alternatives are network monitoring tools that replace PRTG Network Monitor for discovering devices, polling health and bandwidth, and alerting on faults. Common options are Zabbix, Checkmk, ManageEngine OpManager, SolarWinds NPM, and Datadog. The best fit depends on your estate size, your deployment choice, and your pricing model.
Is there a free alternative to PRTG?
Yes. Zabbix, Checkmk Raw Edition, and LibreNMS are free and open source, with no software licence fee. They need more setup skill and a server to run on, and paid support is optional. For a small network, PRTG itself also offers a free tier for up to 100 sensors, which may be enough without switching.
Why do teams leave PRTG?
Teams often leave because sensor-based pricing rises as they add devices and checks, which can push them to disable monitors to stay under a licence cap. Other reasons are a move to cloud infrastructure, a need for MSP features, or a wish for a per-device or open source model. A switch makes sense when the new pricing model and deployment fit the estate better.
Which PRTG alternative is best for small teams?
ManageEngine OpManager and LibreNMS are strong small-team options for different reasons. OpManager gives a guided, supported setup with device-based pricing, while LibreNMS gives fast, free SNMP graphs for a network engineer. A team with Linux skill and a tight budget may prefer Zabbix or Checkmk Raw Edition.
Do these tools monitor servers and cloud as well?
Zabbix, Checkmk, Datadog, and LogicMonitor cover servers and cloud resources as well as networks. LibreNMS and Auvik are more network-focused, while SolarWinds NPM is strongest on network devices. Check the coverage for your exact estate, because network-only tools may need a second tool for server depth.
Can I keep my PRTG sensors and history when I switch?
You can usually export device lists and rebuild checks in the new tool, but full history rarely moves cleanly between systems. Plan to run both tools in parallel for a short period, keep PRTG history for reference, and rebuild alerts and dashboards in the new tool before you turn PRTG off.
Sources
See where you really rank - block by block
ProMapRanker scans Google Maps across a grid of your service area. Simple monthly plans from $19, white-label on every plan.
Start freeKeep reading
 zscaler alternatives
Best Zscaler Alternatives in 2026
Looking for zscaler alternatives? We compare 9 SASE and zero trust platforms on architecture, data protection, pricing, and fit for your network and team.
Read → zapier alternatives free
Best Zapier Alternatives Free in 2026
Nine automation tools for zapier alternatives free in 2026, all with genuinely free tiers, plus free plan limits, starting prices and upgrade paths explained.
Read → which platform is best for online reputation
Which Platform Is Best for Online Reputation in 2026
Wondering which platform is best for online reputation? We compare 8 review, listing, and response tools for small and multi-location businesses and agencies.
Read →