 ProMapRanker
Best AI Bias Audit Services in 2026

Key takeaways
- Governance platforms, observability tools, and specialist auditors solve different problems, so match the tool to whether you need paperwork, monitoring, or an independent check.
- Credo AI and Holistic AI lead on governance and regulatory mapping, while Fiddler AI and Arthur AI lead on live model monitoring and explanation.
- Most enterprise tools in this list are quote-priced, so budget for a sales conversation and a pilot before committing.
- An audit alone does not make a system compliant, and fairness testing needs careful handling of sensitive data, privacy, and consent.
Quick comparison
| Pick | Great for | Pricing starts at | Free tier | |
|---|---|---|---|---|
 Holistic AI | Governance and audit evidence | See website | No | Visit |
 Credo AI | Policy mapping and compliance | See website | No | Visit |
 Fiddler AI | Model observability and explanations | See website | No | Visit |
 Arthur AI | Discovery and monitoring | See website | No | Visit |
 Fairly AI | Governance risk and compliance | See website | No | Visit |
 Monitaur | Model lifecycle governance | See website | No | Visit |
 IBM watsonx.governance | IBM-centred governance | See website | No | Visit |
 BABL AI | Independent bias audits | See website | No | Visit |
 Fairlearn | Open-source fairness testing | Free | Yes | Visit |
The best ai bias audit services
AI bias audit services test whether a model treats groups differently, document what was tested, and help teams track fairness over time. Some tools in this list are platforms you run yourself, while others are specialist firms that carry out an independent audit. This article gives general information only, and an audit alone does not make a system compliant, since compliance also depends on the law that applies, the data used, and the decisions made after the audit.
Holistic AI suits organisations that need a governance platform rather than a single fairness test. It evaluates AI systems across fairness, privacy, and security, maps controls to US and EU requirements, and produces documentation that an internal audit team or a regulator can review. Guided templates help compliance teams get started, which matters when a team has limited AI experience but still faces real regulatory pressure.
The weakness is scope and cost. A broad governance suite needs an owner, a model inventory, and ongoing upkeep, or it becomes a register that nobody trusts. Pricing is quote-based, so small teams cannot budget from the website alone. Holistic AI fits best when governance is a standing programme, not a one-off check, and when the organisation needs evidence across several regulatory frameworks at once.
- Covers fairness, privacy, and security in one governance suite
- Regulatory mapping for US and EU rules
- Audit-ready documentation
- Quote pricing
- Broad scope can overwhelm smaller teams
- Implementation needs dedicated ownership
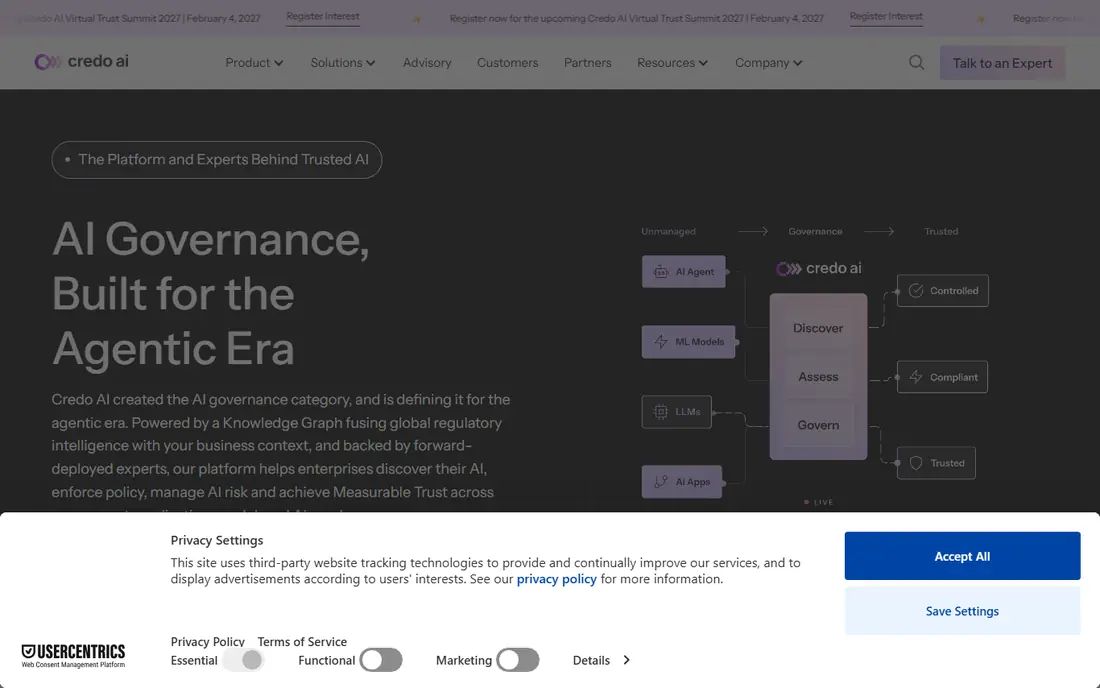
Credo AI is built around the idea that compliance work should start from the rule, not from a generic checklist. It maps statutory and framework requirements into controls, scores model artefacts against those controls, and keeps a registry of AI use cases with risk classifications. Integrations with tools such as Jira and ServiceNow help teams track mitigation steps as ordinary work items rather than separate compliance paperwork.
The honest limit is that Credo AI documents and supervises controls more than it enforces them on live traffic. If a model is not registered accurately, or if mitigation steps are marked complete without evidence, the registry will look better than reality. Pricing is also quote-based. Credo AI fits best when a compliance team needs a clear, auditable programme across many models, and when engineering teams will keep the registry honest.
- Translates regulations into control checklists
- Model registry and risk scoring
- Integrations with workflow tools
- Quote pricing
- Documentation strength exceeds live enforcement
- Needs accurate model registration to be useful
Fiddler AI starts from production behaviour rather than paperwork, which makes it the natural pick when the first problem is seeing what a model actually does after deployment. It monitors models and agents for drift, quality, and behaviour changes, explains individual predictions, and adds a governance, risk, and compliance module on top of that telemetry. Runtime guardrails can also enforce content policy at speed for generative systems.
The trade-off is implementation effort. Observability needs clean data pipelines, baseline definitions, and alert ownership, or alerts become noise that teams ignore. Fiddler records and monitors rather than producing a per-decision authorisation record keyed to identity, so teams that need that specific evidence type should check fit carefully. Fiddler fits best when live behaviour, drift, and explanation matter more than registry paperwork alone.
- Live monitoring for drift and behaviour
- Explainability for individual predictions
- Governance module on top of telemetry
- Quote pricing
- Observability setup needs data pipeline work
- Per-decision audit records are not its core strength
Arthur AI suits organisations whose governance problem starts with not knowing what AI is running. Its discovery tools find models and agents across an environment, then monitoring, evaluation, and guardrails track behaviour and content safety. An open-source evaluation engine also lets technical teams test prompts and models without depending entirely on a vendor dashboard. That combination helps large organisations that have grown AI use through many teams and vendors.
The limit is that discovery is only the first step. Found models still need owners, risk ratings, and mitigation plans, or discovery becomes a list without action. Onboarding can also be heavier than a simple dashboard tool, since containerised components and data connections need engineering time. Arthur fits best when shadow AI, agent sprawl, or unknown model inventory is the main risk, and when a central team can turn discovery into governance.
- Finds models and agents across an environment
- Monitoring plus guardrails
- Open-source evaluation engine
- Quote pricing
- Discovery breadth needs follow-up governance
- Onboarding can be heavier for smaller teams
Fairly AI positions itself as a governance, risk, and compliance platform for AI, with risk assessment workflows and oversight tools for regulated teams. That focus suits organisations that need to show how AI risks were identified, rated, and handled, rather than only showing a fairness metric. Its workflows help compliance, risk, and data science teams work from a shared record instead of separate spreadsheets.
The caution is profile and fit. Fairly AI has a smaller public footprint than Credo AI or IBM, so prospective buyers should ask for references in their sector and for a pilot on a real model before committing. Pricing is quote-based, which makes early budgeting harder. Fairly AI fits best when a regulated team wants a governance-led platform and is willing to validate fit through a pilot.
- Governance, risk, and compliance focus
- Risk assessment workflows
- Suited to regulated teams
- Quote pricing
- Smaller public profile than larger rivals
- Implementation depth varies by use case
Monitaur automates drift, bias, and stress testing across the model lifecycle, while centralising policy, risk, and compliance in one platform. That lifecycle view helps teams that need continuous monitoring rather than a point-in-time audit, since model behaviour can shift as data changes. Audit-ready reporting, vendor controls, and a model registry support teams that must show ongoing oversight to auditors or regulators.
The drawback is enterprise weight. Setup, data connections, and policy configuration take time, and the platform is aimed at mid-market and enterprise teams rather than a single-model startup. Pricing is quote-based. Monitaur fits best when a team runs many models in production, needs continuous bias and drift monitoring, and can staff the governance work that a lifecycle platform requires.
- Centralises policy, risk, and compliance
- Continuous monitoring for drift and bias
- Audit-ready reporting
- Quote pricing
- Enterprise focus means heavier setup
- Smaller teams may find scope excessive
IBM watsonx.governance is the governance module of the watsonx platform, covering model inventory, lifecycle governance, risk and compliance workflows, and factsheets that capture model metadata. Mappings to regulations and frameworks, including the EU AI Act and the NIST AI Risk Management Framework, help large organisations align documentation with the rules they face. For teams already running IBM data and AI tooling, folding governance into the same platform reduces vendor sprawl.
The limit mirrors Credo AI, since its centre of gravity is documenting and managing the programme rather than enforcing policy on each live model call. Teams outside IBM estates should also weigh integration effort against a vendor-neutral platform. Pricing is quote-based. IBM watsonx.governance fits best for large, audited programmes already centred on IBM, and for teams that need formal factsheets and framework mappings.
- Model inventory and lifecycle governance
- Factsheets for model metadata
- Mappings to EU AI Act and NIST AI RMF
- Quote pricing
- Strongest value inside IBM estates
- Documentation focus over live enforcement
BABL AI is a specialist audit firm rather than a software platform, which makes it the right comparison point when independence matters. It carries out bias audits for automated employment decision tools, including audits under New York City Local Law 144, and publishes example audit reports that show impact ratios, group breakdowns, and findings in plain form. An independent auditor can challenge assumptions in a way that an internal dashboard cannot, which is valuable for hiring, lending, and other high-stakes decisions.
The limits are scope and timing. Audit pricing varies by model complexity and data sensitivity, and an audit is a point-in-time check unless monitoring follows it. BABL AI also needs access to relevant data and outputs, which raises privacy and consent questions that must be handled carefully. BABL AI fits best when a regulator, a customer, or a board needs an independent check, and when the organisation will act on findings rather than file the report away.
- Independent third-party audits
- Experience with New York City Local Law 144 audits
- Published audit reports as examples
- Project pricing varies by scope
- Audit is point-in-time unless monitoring follows
- Needs access to data and model outputs
Fairlearn is an open-source, community-driven project that helps data scientists assess and improve fairness in machine learning models. It provides fairness metrics, disparity assessment, and mitigation approaches that technical teams can run in their own environment, without a vendor contract. For learning, research, and prototyping, it is the lowest-cost way to test whether a model shows group disparities, and its documentation explains metric choices in accessible terms.
The weakness is that Fairlearn is a toolkit, not a governance programme. It offers no vendor support, no model registry, and no audit-ready workflow out of the box, so teams must build reporting, ownership, and monitoring themselves. It also needs data science skill to use well, since metric choice and group definitions shape results. Fairlearn fits best for technical teams that want to test fairness early, and for organisations that will pair it with a governance process rather than treating a metric as proof of compliance.
- Free and open source
- Fairness metrics and mitigation tools
- Good for learning and prototyping
- Needs data science skill
- No vendor support or governance workflow
- Teams must build reporting themselves
How we picked these
We compared official product pages, governance documentation, and public comparisons of responsible AI platforms in October 2026. We included governance suites, observability tools, a specialist auditor, and an open-source toolkit, because bias audit work spans all four, and a list of only one type would mislead buyers. Where pricing was not published, we listed See website rather than a third-party estimate. This article is general information only, not legal or compliance advice, and an audit alone does not make a system compliant.
How to run a bias audit that means something
Start by defining the decision, the affected groups, and the fairness question before choosing a metric, since different metrics can point in different directions. A hiring tool, a lending model, and a content system raise different fairness questions, and a single metric rarely answers all of them. Next, handle sensitive data with care, since fairness testing often needs group data that is itself sensitive. Use lawful bases, minimisation, access controls, and consent where required, and do not collect sensitive attributes you do not need for the test.
Then test on representative data, document sample sizes and exclusions, and report uncertainty rather than a single clean number. Small groups need special care, since a rate based on a handful of cases can mislead. After testing, decide on mitigation, retest, and monitor in production, because a model that was fair at launch can drift as data changes. Finally, keep an audit trail that shows what was tested, what was found, and what changed as a result. That trail is what turns a fairness metric into governance evidence.
Frequently asked questions
What is an AI bias audit?
An AI bias audit tests whether an AI system produces different outcomes for different groups, and documents how the test was done. It usually covers data, model outputs, group metrics, and limitations. It is a diagnostic and governance step, not a guarantee that a system is fair or lawful.
Does passing a bias audit mean a system is compliant?
No, an audit alone does not make a system compliant. Compliance depends on the specific law, the use case, the data handling, and the actions taken after the audit. An audit can support compliance work, but it does not replace legal advice or regulatory review.
How often should AI models be audited for bias?
At minimum, audit before deployment, after major updates, and on a regular schedule, with more frequent monitoring for high-risk systems such as hiring or lending. Models can drift as data changes, so a one-time audit can go stale. Continuous monitoring helps catch drift between formal audits.
Do bias audits need sensitive personal data?
Often yes, since group comparisons need group information, but that data must be handled lawfully and with care. Use minimisation, access controls, and clear purposes, and consider privacy-preserving methods where available. Note privacy and consent requirements early, since they shape what testing is possible.
What is the difference between a platform and an independent auditor?
A platform is software your team uses to test, monitor, and document models on an ongoing basis. An independent auditor is a third party that carries out a check and reports findings. Many organisations use both, with a platform for ongoing work and an auditor for an independent, point-in-time check.
Can open-source tools replace an enterprise bias audit platform?
Open-source tools such as Fairlearn can handle fairness metrics and early testing, but they do not provide governance workflows, vendor support, or audit-ready reporting on their own. They suit technical teams that will build those processes themselves. Regulated teams often pair open-source testing with a governance platform or an independent audit.
Sources
See where you really rank - block by block
ProMapRanker scans Google Maps across a grid of your service area. Simple monthly plans from $19, white-label on every plan.
Start freeKeep reading
 worlds best local seo company
8 Worlds Best Local SEO Companies for Map Pack Growth in 2026
Compare the worlds best local seo company options for Google Business Profile work, citations, reviews, and multi-location rankings and reporting in 2026.
Read → world's best web hosting company
World's Best Web Hosting Company in 2026
Searching for the world's best web hosting company? We compared 10 hosts on price, renewal rates, speed, and support to help you choose well today in 2026.
Read → who's got the best nanny tax services
Who's Got the Best Nanny Tax Services in 2026
We answer who's got the best nanny tax services, comparing full filing, back taxes, software, and pricing so families can handle nanny taxes correctly.
Read →