 ProMapRanker
Best AI Evaluation Tools for Production in 2026

LangChain teams needing tracing and review · Pricing starts at: $39 per seat per month
Key takeaways
- Production evaluation needs tracing plus scoring, not scoring alone
- Open-source frameworks cost nothing to run but still cost judge model tokens
- Human annotation matters most for subjective quality and safety judgments
- CI gates catch regressions before a prompt or model change reaches users
- Sampling production traffic gives a truer picture than a fixed test set alone
Quick comparison
| Pick | Great for | Pricing starts at | Free tier | |
|---|---|---|---|---|
| LangSmith | LangChain teams needing tracing and review | $39 per seat per month | Yes | Visit |
 Langfuse | open-source tracing and evaluation | See website | Yes | Visit |
 DeepEval | pytest-style automated AI testing | Free | Yes | Visit |
 Ragas | retrieval-focused evaluation for RAG apps | Free | Yes | Visit |
 Promptfoo | prompt and model comparison in CI | Free | Yes | Visit |
 Braintrust | production evaluation with collaboration | $249 per month | Yes | Visit |
 Arize Phoenix | open-source observability and evaluation | Free | Yes | Visit |
 Confident AI | hosted platform for DeepEval users | $9.99 per user per month | Yes | Visit |
 TruLens | explainable RAG evaluation for researchers | Free | Yes | Visit |
The best AI evaluation tools for production
We compared tools that evaluate language model apps in production or in CI, and we weighed scoring options, tracing, human review, self-hosting, and price. Our pick for most teams is an open-source framework for automated checks plus a hosted platform for tracing and review when volume grows.
For LangChain teams needing tracing and review, LangSmith is a practical first choice. It ties traces, datasets, and human feedback together, which makes it easier to find why a model answer changed after a prompt edit. Its main strengths are deep langchain integration; annotation queues; tracing and production monitoring. For many readers, that combination covers the most common jobs without adding extra steps or a steep learning curve.
In daily use, the workflow stays short for repeat jobs, and most settings are easy to find without a manual. On the other side, free tier is small for active teams; best value inside langchain. The catch is worth weighing before you commit, especially if you work with sensitive files every day.
- Deep LangChain integration
- Annotation queues
- Tracing and production monitoring
- Free tier is small for active teams
- Best value inside LangChain
If open-source tracing and evaluation describes your work, Langfuse deserves a close look. It captures traces and lets teams attach scores to them, so production samples can feed back into evaluation datasets. Its main strengths are open-source core; self-hosting option; tracing plus custom scores. For many readers, that combination covers the most common jobs without adding extra steps or a steep learning curve.
In daily use, the workflow stays short for repeat jobs, and most settings are easy to find without a manual. On the other side, paid plan details vary by source; setup takes engineering time. That balance of strength and limits is what should drive your choice, not the headline feature list.
- Open-source core
- Self-hosting option
- Tracing plus custom scores
- Paid plan details vary by source
- Setup takes engineering time
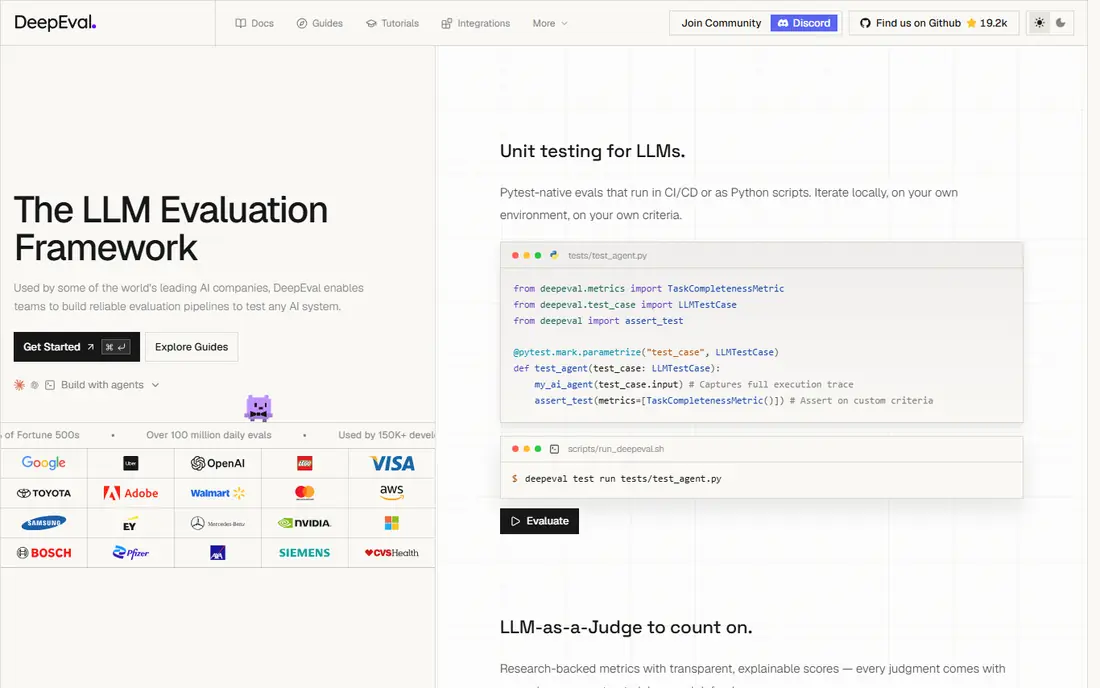
DeepEval stands out for pytest-style automated AI testing, and it is easy to see why. It lets engineers write evaluations as code with research metrics for faithfulness, relevance, and hallucination, which fits CI pipelines well. Its main strengths are more than a dozen built-in metrics; pytest-native workflow; ci integration. For many readers, that combination covers the most common jobs without adding extra steps or a steep learning curve.
In daily use, the workflow stays short for repeat jobs, and most settings are easy to find without a manual. On the other side, hosted platform is a separate paid product; judge costs still apply. Check the current plan details before you pay, since limits and included tools change over time.
- More than a dozen built-in metrics
- Pytest-native workflow
- CI integration
- Hosted platform is a separate paid product
- Judge costs still apply
People who need retrieval-focused evaluation for RAG apps often land on Ragas after comparing a few options. It measures whether retrieved context supports the answer, which is the key question for retrieval apps that other general tools answer less directly. Its main strengths are rag-specific metrics; context precision and recall; dataset export. For many readers, that combination covers the most common jobs without adding extra steps or a steep learning curve.
In daily use, the workflow stays short for repeat jobs, and most settings are easy to find without a manual. On the other side, no built-in tracing or annotation; rag focus limits general use. If that trade-off fits your daily work, it is a solid pick; if not, another tool below may fit better.
- RAG-specific metrics
- Context precision and recall
- Dataset export
- No built-in tracing or annotation
- RAG focus limits general use
Promptfoo is built with prompt and model comparison in CI in mind, rather than as an afterthought. It runs prompts against many models and checks outputs with rules or judge models, which makes prompt regressions visible in pull requests. Its main strengths are custom assertions; red-team attack tests; multi-model comparison. For many readers, that combination covers the most common jobs without adding extra steps or a steep learning curve.
In daily use, the workflow stays short for repeat jobs, and most settings are easy to find without a manual. On the other side, no hosted annotation workflow; enterprise features are quote-based. The catch is worth weighing before you commit, especially if you work with sensitive files every day.
- Custom assertions
- Red-team attack tests
- Multi-model comparison
- No hosted annotation workflow
- Enterprise features are quote-based
Among tools for production evaluation with collaboration, Braintrust keeps the workflow short and clear. It combines evaluation datasets, scoring, and production logging in one interface, which helps product and engineering teams review the same cases. Its main strengths are generous free span allowance; polished review interface; dataset versioning. For many readers, that combination covers the most common jobs without adding extra steps or a steep learning curve.
In daily use, the workflow stays short for repeat jobs, and most settings are easy to find without a manual. On the other side, paid entry is higher than open-source options; no self-hosting for most teams. That balance of strength and limits is what should drive your choice, not the headline feature list.
- Generous free span allowance
- Polished review interface
- Dataset versioning
- Paid entry is higher than open-source options
- No self-hosting for most teams
For open-source observability and evaluation, Arize Phoenix is a practical first choice. It traces model calls and surfaces retrieval and response patterns, which helps teams debug production issues before writing new evals. Its main strengths are opentelemetry tracing; rag visualization; self-hosting option. For many readers, that combination covers the most common jobs without adding extra steps or a steep learning curve.
In daily use, the workflow stays short for repeat jobs, and most settings are easy to find without a manual. On the other side, cloud pricing varies; enterprise features need a paid plan. Check the current plan details before you pay, since limits and included tools change over time.
- OpenTelemetry tracing
- RAG visualization
- Self-hosting option
- Cloud pricing varies
- Enterprise features need a paid plan
If hosted platform for DeepEval users describes your work, Confident AI deserves a close look. It gives DeepEval users a hosted place to run, store, and share evaluations without managing their own evaluation infrastructure. Its main strengths are hosted deepeval runs; team collaboration; tracing allowance on entry plans. For many readers, that combination covers the most common jobs without adding extra steps or a steep learning curve.
In daily use, the workflow stays short for repeat jobs, and most settings are easy to find without a manual. On the other side, entry plan limits tracing volume; judge token costs are separate. If that trade-off fits your daily work, it is a solid pick; if not, another tool below may fit better.
- Hosted DeepEval runs
- Team collaboration
- Tracing allowance on entry plans
- Entry plan limits tracing volume
- Judge token costs are separate
TruLens stands out for explainable RAG evaluation for researchers, and it is easy to see why. It scores retrieval, grounding, and answer relevance as a linked set, which helps research teams explain why a RAG answer should or should not be trusted. Its main strengths are rag triad feedback functions; model versioning; open-source code. For many readers, that combination covers the most common jobs without adding extra steps or a steep learning curve.
In daily use, the workflow stays short for repeat jobs, and most settings are easy to find without a manual. On the other side, smaller community than larger platforms; enterprise support is separate. The catch is worth weighing before you commit, especially if you work with sensitive files every day.
- RAG triad feedback functions
- Model versioning
- Open-source code
- Smaller community than larger platforms
- Enterprise support is separate
How we picked these
We compared vendor pricing pages, documentation, and comparison guides for each tool, and we favored tools with clear production or CI use, not only notebook demos. We noted free tiers, self-hosting, and whether pricing is published. Prices we could not verify are shown as See website.
How to choose an AI evaluation tool for production
Separate offline evals from production monitoring
Offline evals test a fixed dataset before release. Production monitoring samples live traffic and finds drift. Most teams need both, and one tool rarely does both equally well.
Pick metrics for your app type
RAG apps need faithfulness and context metrics. Chat apps need relevance, safety, and multi-turn checks. Agent apps need trajectory checks. Start with three metrics you trust, not twenty you ignore.
Budget for judge costs
Open-source tools are free to run, but judge model calls cost money at scale. Estimate samples per day and judge calls per sample before you choose a sampling rate.
Keep humans in the loop for judgment calls
Automated scores miss tone, safety nuance, and business context. Use annotation queues for a sample of cases, and use those labels to check whether your automated scores agree.
Frequently asked questions
What is an AI evaluation tool?
It is software that scores language model outputs against metrics, datasets, or human labels, so teams can compare prompts, models, and code changes before and after release.
How is production evaluation different from testing?
Testing uses a fixed dataset before release. Production evaluation samples live traffic, tracks scores over time, and catches drift, bad data, or model changes after release.
Are open-source evaluation tools really free?
The code is free, but judge model calls, hosting, and engineering time still cost money. Hosted platforms charge for convenience, storage, and collaboration instead.
Do I need human annotation?
For subjective quality, safety, and brand fit, yes. Automated judges are fast and consistent, but humans catch nuance that judges miss, especially on edge cases.
Which tool is best for RAG apps?
Ragas and DeepEval suit RAG metrics best, while Langfuse and Arize Phoenix add tracing. Many teams pair a RAG framework with a tracing platform for full coverage.
Sources
See where you really rank - block by block
ProMapRanker scans Google Maps across a grid of your service area. Simple monthly plans from $19, white-label on every plan.
Start freeKeep reading
 zeffy payment processor stripe alternatives
Zeffy and Stripe Alternatives for Nonprofits in 2026
Explore zeffy payment processor stripe alternatives for nonprofits. We compare 8 fundraising platforms on fees, donor tools, and nonprofit focus. Check fees.
Read → workday alternatives
Workday Alternatives in 2026
Workday alternatives compared: we review 8 HR and payroll platforms that replace Workday, with pricing, strengths and honest limits for each team size.
Read → what's the best weather app
What's the Best Weather App in 2026
Wondering what's the best weather app? We compare 10 free and paid apps for forecasts, radar, alerts, and Colorado mountain weather for everyday and storm use.
Read →